
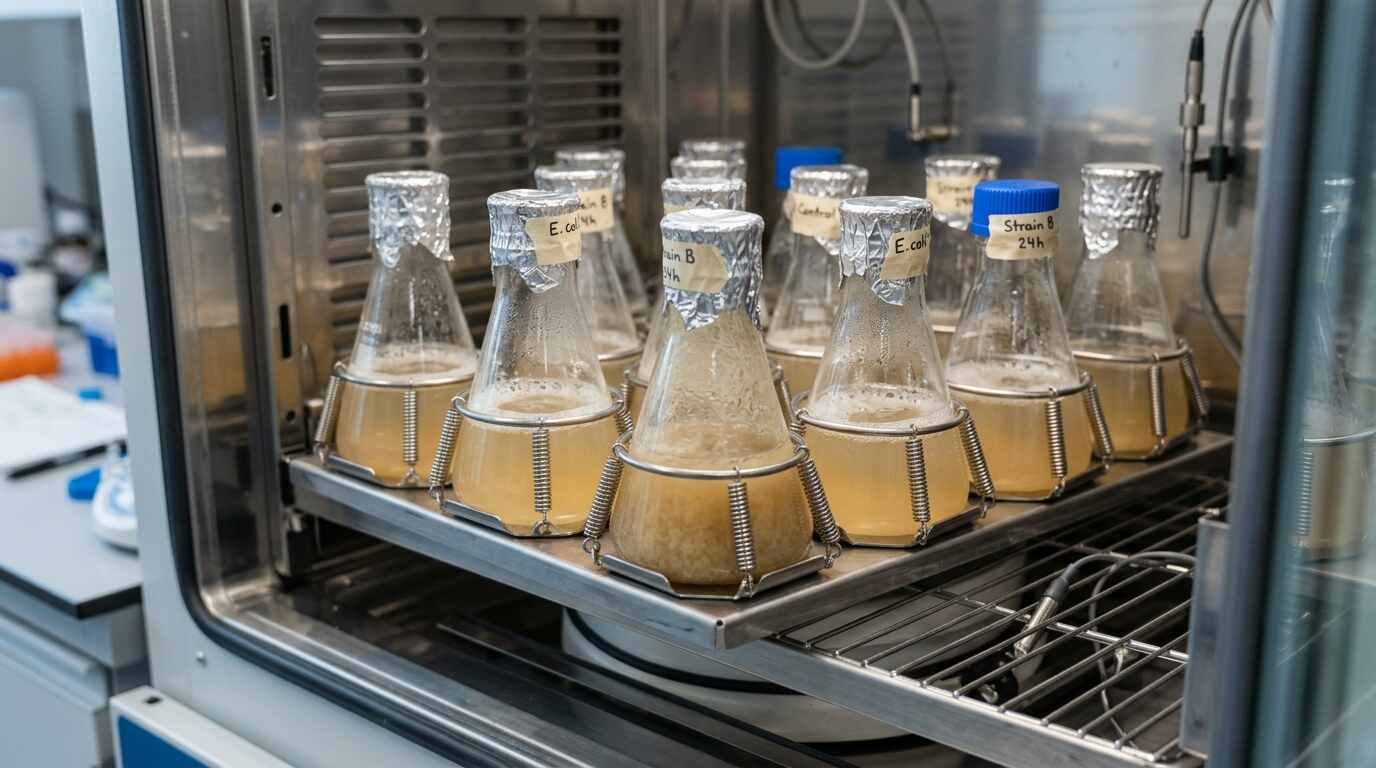
Gould said a replay of life's tape would produce a different world. Experiments since then show both contingency and repeatability; this article weighs the evidence and runs a small replay simulation on rugged fitness landscapes.
Is evolution predictable, or would a second run of life’s history produce a world we could not recognize? Stephen Jay Gould framed the question in 1989 with a thought experiment: rewind the tape of life to the Cambrian, let it play again, and see whether anything like us turns up. Thirty-seven years later, biologists can replay small pieces of that tape in flasks, in lizard populations on tiny islands and inside a single bacterial enzyme. They still disagree about what the replays mean.
The question matters beyond intellectual taste. If adaptation follows repeatable routes, then antibiotic resistance, tumor evolution and viral escape can in principle be forecast, and drug schedules can be designed against the most likely path. If each lineage’s history sends it somewhere idiosyncratic, forecasting will stay limited to short horizons and broad statements. Public interest is visible too: university press offices ran headlines such as “Replaying the tape of life: Is it possible?” when a major review appeared in 2018 (WashU Source, 2018; MSU Today, 2018).
This article separates what experiments have shown from what remains argument, sets out three competing answers, and adds a small simulation built for this piece: many replicate populations started from one genotype on fitness landscapes of increasing ruggedness, to see how often they end up on the same peak. A companion explainer on this site, Is Evolution Random?, covers the basics of mutation, selection and drift; here the focus is narrower, on repeatability.
Stating the open question precisely
“Predictable” hides at least three different claims, and much of the debate comes from running them together.
- Phenotypic repeatability: do independent lineages under the same conditions arrive at similar traits, such as higher fitness, shorter limbs or a camera eye?
- Genetic repeatability: do they get there through the same genes, the same mutations, the same order of steps?
- Historical contingency: does an outcome depend on earlier, chance events, so that a replay from a different point in history would diverge?
These can come apart. Two populations might reach equal fitness through entirely different mutations; that is repeatable at one level and contingent at another. The unsettled question is which level dominates over which timescale, and whether there is a general rule telling us in advance how repeatable a given system will be. Nobody has that rule yet.
What experiments have established
The strongest evidence comes from Richard Lenski’s Long-Term Evolution Experiment (LTEE), started in 1988 with twelve populations of Escherichia coli founded from a common ancestor and grown in the same glucose-limited medium. Early results showed the populations gaining fitness along broadly similar trajectories while diverging in other traits such as cell size (Lenski and Travisano 1994). Fitness, the trait selection acts on directly, looked repeatable; less-constrained features did not.
Then one population did something none of the others did. The medium contains citrate, which E. coli normally cannot use in the presence of oxygen. After more than 30,000 generations, a single population, Ara-3, evolved that ability, called Cit+. Zachary Blount and colleagues froze samples throughout the experiment, so they could rerun history from different time points. They opened their report bluntly:
“The role of historical contingency in evolution has been much debated, but rarely tested.”
Blount, Borland and Lenski, 2008
Their replays from frozen clones answered it directly: “we observed a significantly greater tendency for later clones to evolve Cit+” (Blount et al. 2008). Something earlier in Ara-3’s history, a potentiating mutation or set of mutations, had made the innovation more accessible. That is contingency demonstrated in a laboratory with replication and controls rather than inferred from fossils.
At the molecular scale, the opposite tendency has been shown just as cleanly. Daniel Weinreich and colleagues took a beta-lactamase allele in which five point mutations together raise antibiotic resistance roughly 100,000-fold. Of the 120 orders in which those five mutations could be acquired, 102 were inaccessible to natural selection, because some steps would lower resistance along the way (Weinreich et al. 2006). Their conclusion was that “the protein tape of life may be largely reproducible and even predictable.” Epistasis, the dependence of one mutation’s effect on others, closed most routes and funneled evolution into a few.
So both results stand. History mattered for citrate use; constraint mattered for the enzyme. The question is how they combine.
Answer one: contingency rules
Gould’s position in Wonderful Life was that the broad shape of animal life reflects which lineages happened to survive early extinctions, not which were best designed, and that a replay would very likely produce no humans. The steelmanned version does not deny selection. It says that selection operates on whatever variation is present, that variation arises by chance, and that early chance events change which later steps are possible. Cit+ is the experimental emblem: a potentiating step with no obvious benefit at the time made a major innovation possible much later.
Further support comes from experiments summarized by Blount, Lenski and Losos (2018). In Pseudomonas, a bet-hedging strategy evolved in only two of twelve replicates and depended on an earlier mutation that was detrimental in the ancestor. In green algae grown under elevated carbon dioxide, five replicate populations split into two quite different adaptive responses. Phage lambda’s use of a new host receptor depended on mutations in its coevolving host.
The weakness of this view is scale. Most replay experiments are short, and the cases of striking contingency are noticeable precisely because they are exceptions. A theory of evolution in which anything can happen also predicts little, which makes it hard to test.
Answer two: convergence and constraint rule
The opposite case, argued most forcefully by the paleontologist Simon Conway Morris in Life’s Solution (2003), points to how often unrelated lineages have reached the same solution: camera eyes in vertebrates and octopuses, streamlined bodies in sharks and dolphins, similar body plans in marsupial and placental mammals. If the space of workable designs is small, selection will keep finding the same ones whatever the starting point. The evolution of complex organs, discussed in How Did the Eye Evolve?, is the usual centerpiece.
Field and lab evidence supports a version of this. Caribbean Anolis lizards have evolved similar sets of habitat specialists on different islands, and brown anoles moved onto narrow perches evolved shorter limbs in repeatable ways. Freshwater sticklebacks lost armor plates over and over through repeated fixation of the same Ectodysplasin alleles. LTEE fitness rose in parallel across all twelve flasks. All of these are reviewed in Blount et al. (2018). Weinreich’s enzyme adds a mechanism: when epistasis makes most paths downhill, the remaining few become predictable.
The objection is selection bias. Convergent examples are collected because they are striking; nobody catalogues all the times lineages under similar pressures did different things. Many convergences also share ancestral genetic variation, as the sticklebacks do, so they test how predictable selection is on standing variation rather than whether new mutations would be found again.
Answer three: it depends on level, history and landscape
The position most working evolutionary biologists now hold is a conditional one, and the 2018 review by Blount, Lenski and Losos states it explicitly: evolution is both contingent and deterministic, with parallelism common at broad levels such as fitness and phenotype, less common at the level of particular mutations, and less likely as lineages accumulate different histories. That is a description, though, not yet a predictive theory.
The missing piece is a measure of the fitness landscape itself. De Visser and Krug (2014) reviewed empirical landscapes, in which researchers measure fitness for all combinations of a handful of mutations, and argued that the genotype-fitness map, especially sign epistasis, is what links mechanism to predictability. A smooth landscape with one peak should make evolution highly repeatable. A rugged one, with many local peaks separated by valleys, should let small early differences send replicates to different summits.
That intuition has been formalized for decades in the NK model of Kauffman and Levin (1987), where N loci each interact with K others. When K is zero the landscape is smooth; when K is N minus 1 it is maximally rugged. It is a useful toy for asking how much ruggedness erodes repeatability, which is exactly what the next section does.
A small replay simulation on NK landscapes
The simulation built for this article asks a narrow question: if many populations start from the same genotype on the same landscape, how often do two of them finish on the same fitness peak, and how does that change as ruggedness rises?
The setup, in plain terms:
- Genomes have 12 binary loci, so every one of the 4,096 genotypes can be enumerated and every local peak counted exactly.
- For each ruggedness level K in {0, 1, 2, 4, 6, 8, 11}, ten random NK landscapes were drawn.
- On each landscape, 40 replicate populations started from one shared random genotype and evolved for 600 generations under Wright-Fisher reproduction with selection (fitness weight exp(40 × f)) and a genomic mutation rate of 0.01 per individual per generation.
- This was done at population sizes of 100 and 1,000, using separately drawn landscapes for each size.
- At the end, each population’s most common genotype was assigned to the local peak whose basin contains it, found by steepest ascent.
The main statistic is the probability that two randomly chosen replicates ended on the same peak. Seeds were fixed, and the run took about five minutes on a single CPU. The core functions:
import numpy as np
L = 12                      # loci; 2^12 = 4096 genotypes, enumerated exactly
G_ALL = np.arange(2**L)
BITS = (G_ALL[:, None] >> np.arange(L)) & 1

def nk_landscape(K, rng):
    nb = [np.r_[i, rng.choice(np.delete(np.arange(L), i), K, replace=False)] for i in range(L)]
    tab = rng.random((L, 2**(K + 1)))
    f = np.zeros(2**L)
    for i in range(L):
        idx = (BITS[:, nb[i]] * (1 << np.arange(K + 1))).sum(1)
        f += tab[i, idx]
    return f / L

def replay(f, start, R, P, gens, beta, U, rng):
    pop = np.full((R, P), start)
    off = np.arange(R)[:, None]
    for _ in range(gens):
        w = np.exp(beta * (f[pop] - f[pop].max(1, keepdims=True)))
        c = np.cumsum(w, 1); c = c / c[:, -1:] + off      # rows stacked end to end
        u = rng.random((R, P)) + off
        pick = np.minimum(np.searchsorted(c.ravel(), u.ravel()), R * P - 1)
        pop = pop.ravel()[pick].reshape(R, P)
        m = rng.poisson(R * P * U)                         # new mutations
        if m:
            flat = pop.ravel(); np.bitwise_xor.at(flat, rng.integers(0, R * P, m),
                                                  1 << rng.integers(0, L, m))
            pop = flat.reshape(R, P)
    modes = [np.bincount(r).argmax() for r in pop]
    return np.array([climb(g, f) for g in modes]), np.array([f[g] for g in modes])

def same_peak(ends):        # P(two random replicates end on the same peak)
    _, n = np.unique(ends, return_counts=True); R = len(ends)
    return (n * (n - 1)).sum() / (R * (R - 1))
Results, averaged over ten landscapes per cell (population size 100 / 1,000):
| Ruggedness K | Local peaks (mean) | P(two replicates share a peak) | Distinct endpoints of 40 | Share reaching global peak | Fitness CV (%) |
|---|---|---|---|---|---|
| 0 | 1.0 / 1.0 | 1.00 / 1.00 | 1.0 / 1.0 | 1.00 / 1.00 | 0.0 / 0.0 |
| 1 | 4.4 / 5.4 | 0.60 / 0.72 | 3.0 / 1.7 | 0.37 / 0.64 | 2.7 / 1.2 |
| 2 | 13.1 / 14.2 | 0.43 / 0.62 | 3.7 / 3.3 | 0.29 / 0.25 | 3.0 / 2.2 |
| 4 | 40.4 / 35.3 | 0.36 / 0.60 | 6.7 / 3.4 | 0.02 / 0.16 | 4.5 / 2.3 |
| 6 | 87.7 / 89.7 | 0.37 / 0.55 | 8.5 / 4.0 | 0.03 / 0.20 | 3.4 / 2.1 |
| 8 | 160.3 / 157.8 | 0.28 / 0.58 | 8.4 / 4.2 | 0.01 / 0.00 | 5.5 / 3.6 |
| 11 | 317.1 / 308.7 | 0.26 / 0.30 | 10.0 / 9.0 | 0.01 / 0.01 | 4.5 / 3.9 |
Four patterns stand out. First, repeatability of the endpoint fell steadily with ruggedness, from certainty on the smooth landscape to roughly a one-in-four or one-in-three chance that two replicates share a peak at maximal ruggedness. Second, it fell far more slowly than the count of peaks would suggest. At K = 11 there were over 300 local peaks, so picking one at random would give two replicates a shared endpoint well under 1% of the time; the simulated populations matched about 26 to 30% of the time. Shared starting points and unequal basins kept outcomes concentrated. Third, larger populations were usually more repeatable at intermediate ruggedness (0.60 versus 0.36 at K = 4), consistent with a bigger mutation supply letting selection pick the best available neighbor rather than whichever arrived first. Fourth, fitness stayed similar even when genotypes did not: the coefficient of variation in final fitness never exceeded about 6%, while the number of distinct endpoints among 40 replicates climbed to 9 or 10.
That last pattern is a toy echo of the LTEE: parallel fitness, divergent genotypes.
What the simulation does and does not show
It shows that, in this model, ruggedness reduces genetic repeatability gradually rather than abruptly, and that the number of peaks on a landscape is a poor guide to how many outcomes will actually occur. It also shows that population size and mutation supply change repeatability on the same landscape, so “how predictable is evolution here?” has no answer without demographic details.
It does not show anything about real organisms directly. NK landscapes are random by construction, while real landscapes are shaped by biophysics. Twelve loci are tiny. Six hundred generations with these settings mostly capture climbing to the first reachable peak, not valley-crossing over long timescales, and there is no recombination, no changing environment and no coevolution, which are exactly the conditions under which Gould’s contingency should be strongest. With ten landscapes per cell the estimates are noisy (the K = 8 large-population value, 0.58, sits above K = 6), and the two population sizes were run on different landscape draws, so the comparison between them is unpaired. Treat the numbers as an illustration of a mechanism, not a measurement.
The author’s reading, and what would settle it
What follows is opinion, labeled as such. My reading of the evidence is that the Gould-versus-convergence framing has largely dissolved into the conditional answer, but the conditional answer is not yet a theory, because it does not say in advance how repeatable a given system will be. The open question has shifted from “is evolution predictable?” to “which measurable properties of a system predict its repeatability, and over what horizon?” The candidate properties are landscape ruggedness (especially sign epistasis), population size and mutation supply, the amount of shared standing variation, and the length of divergent history.
Several studies could move this from description to prediction:
- Measure the landscape, then forecast the replay. For a system with an empirically mapped landscape, publish a quantitative prediction of the endpoint distribution before running dozens of replicate populations. If the measured frequency of shared endpoints falls outside the predicted interval, the landscape-based view loses ground.
- Vary population size on one landscape. The simulation predicts that, at intermediate ruggedness, larger populations repeat more often. A microbial experiment with a factorial design of population size and replicate count can test that directly.
- Grade history. Extending the Cit+ approach, replay from many time points in several lineages and fit how fast the probability of re-evolving an innovation changes with time since divergence. The conditional view predicts that convergence declines with divergent history; the slope is the useful number.
- Track forecast accuracy in the wild. Antibiotic resistance and viral evolution already generate forecasts. Scoring those forecasts against what happens over years would show where predictability holds outside the lab.
One prediction from my reading that could fail: in experiments where fitness and genotype are both measured, fitness will continue to be more repeatable than genotype across systems. A study showing the reverse at scale would be a genuine surprise.
None of this tells us whether humans would reappear on a rerun of the Cambrian. That question is probably out of reach for experiment, and the honest answer is that we do not know. Whether our own species is still evolving in measurable ways is a separate and more tractable question, covered in Are Humans Still Evolving?
Common questions
What did Gould mean by replaying the tape of life?
In Wonderful Life (1989), Gould imagined rewinding history to the time of the Burgess Shale fauna and letting it run again. He argued the rerun would almost certainly produce a different set of surviving lineages and probably no humans. It was a thought experiment about contingency, not a procedure anyone could carry out at that scale.
Has anyone actually replayed evolution?
Yes, on small scales. The LTEE keeps frozen samples of its populations, which lets researchers restart evolution from earlier points, as Blount and colleagues did for citrate use. Other labs run many replicate populations from one ancestor and compare outcomes, and field studies on island lizards have tested repeatability in nature.
If fitness evolves predictably, why does the genetic route matter?
Because many practical forecasts depend on genes, not just fitness. Predicting which resistance mutation a pathogen will acquire, or which mutation will let a tumor escape a drug, requires genetic repeatability. Experiments and the simulation here both suggest that fitness can converge while the underlying mutations differ.
Does a rugged fitness landscape make evolution unpredictable?
It makes it less repeatable, but not random. In the simulation built for this article, replicate populations on the most rugged landscapes still shared an endpoint far more often than chance would imply, because basins of attraction differ in size and replicates shared a starting point. Real landscapes may behave differently, which is why measuring them matters.
Further reading
- Wonderful Life: The Burgess Shale and the Nature of History by Stephen Jay Gould. The book that posed the replay-the-tape thought experiment. See it on Amazon (affiliate link)
- Life's Solution: Inevitable Humans in a Lonely Universe by Simon Conway Morris. The fullest statement of the convergence-and-constraint answer. See it on Amazon (affiliate link)
- Improbable Destinies: Fate, Chance, and the Future of Evolution by Jonathan B. Losos. A readable account of replay experiments by one of the researchers who ran them. See it on Amazon (affiliate link)
As an Amazon Associate I earn from qualifying purchases. A commission may be earned if you buy through this link, at no extra cost to you.
References
- Gould, S. J. (1989). Wonderful Life: The Burgess Shale and the Nature of History. W. W. Norton.
- Lenski, R. E., and Travisano, M. (1994). Dynamics of adaptation and diversification: a 10,000-generation experiment with bacterial populations. Proceedings of the National Academy of Sciences. PMC44287
- Blount, Z. D., Borland, C. Z., and Lenski, R. E. (2008). Historical contingency and the evolution of a key innovation in an experimental population of Escherichia coli. PNAS 105(23): 7899-7906. PMC2430337
- Weinreich, D. M., Delaney, N. F., DePristo, M. A., and Hartl, D. L. (2006). Darwinian evolution can follow only very few mutational paths to fitter proteins. Science 312: 111-114. doi:10.1126/science.1123539
- Blount, Z. D., Lenski, R. E., and Losos, J. B. (2018). Contingency and determinism in evolution: Replaying life’s tape. Science 362(6415): eaam5979. doi:10.1126/science.aam5979
- de Visser, J. A. G. M., and Krug, J. (2014). Empirical fitness landscapes and the predictability of evolution. Nature Reviews Genetics 15: 480-490. doi:10.1038/nrg3744
- Kauffman, S., and Levin, S. (1987). Towards a general theory of adaptive walks on rugged landscapes. Journal of Theoretical Biology 128: 11-45. doi:10.1016/S0022-5193(87)80029-2
- Conway Morris, S. (2003). Life’s Solution: Inevitable Humans in a Lonely Universe. Cambridge University Press.
- Washington University in St. Louis, The Source (2018). Replaying the tape of life: Is it possible? source.washu.edu
- Michigan State University, MSU Today (2018). Is it possible to replay the tape of life? msutoday.msu.edu